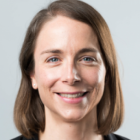
Ameet Talwalkar is an assistant professor in the Machine Learning Department at Carnegie Mellon University, and also co-founder and chief scientist at Determined AI. He led the initial development of the MLlib project in Apache Spark, is a co-author of the textbook Foundations of Machine Learning (MIT Press), and created an award-winning edX MOOC on distributed machine learning.
Areas of Expertise
Machine Learning
Algorithms
Computational Biology
Bioinformatics
Data Mining
Media Appearances
Pittsburgh’s AI-Powered Renaissance
CMU News online
2024-10-09
"CMU has an unparalleled degree of expertise in AI among its faculty and students. In the context of human-centric AI, the fact that we have distinct departments in machine learning, human-computer interaction, and language technologies, coupled with a highly collaborative research environment, gives CMU and Pittsburgh a technical advantage. We have a burgeoning startup scene, in part based on academic spinouts, including two of the fastest growing AI startups in the world: Abridge AI and Skild AI."
Researchers outline promises, challenges of understanding AI for biological discovery
Medical Xpress online
2024-08-09
"Interpretable machine learning has generated significant excitement as machine learning and artificial intelligence tools are being applied to increasingly important problems," said Ameet Talwalkar, an associate professor in CMU's Machine Learning Department (MLD).
Determined AI makes its machine learning infrastructure free and open source
TechCrunch online
2020-04-29
“They’re using things like TensorFlow and PyTorch,” said Chief Scientist Ameet Talwalkar. “A lot of the way that work is done is just conventions: How do the models get trained? Where do I write down the data on which is best? How do I transform data to a good format? All these are bread and butter tasks. There’s tech to do it, but it’s really the Wild West. And the amount of work you have to do to get it set up… there’s a reason big tech companies build out these internal infrastructures.”
AI in the 2020s Must Get Greener—and Here’s How The push for energy efficient “Green AI” requires new strategies | Opinion
IEEE Spectrum online
2020-02-14
The environmental impact of artificial intelligence (AI) has been a hot topic as of late—and I believe it will be a defining issue for AI this decade. The conversation began with a recent study from the Allen Institute for AI that argued for the prioritization of “Green AI" efforts that focus on the energy efficiency of AI systems.
Carnegie Mellon University’s artificial intelligence experts come from a wide range of backgrounds and perspectives, representing fields including computer science, sustainability, national security and entrepreneurship.
Ahead of the AI Horizons Summit highlighting the city's commitment to responsible technology, CMU experts weighed in on why they see Pittsburgh as a hub for human-centered AI.
Media
Social
Accomplishments
Best Paper Award, Conference on Human Computation and Crowdsourcing (HCOMP)
Speaker: AI in Financial Services: Transforming the Sector for a Better World
AI Horizons Pittsburgh Summit Pittsburgh, PA
2024-10-14
Articles
This time is different: An observability perspective on time series foundation models
Advances in neural information processing systems
Ben Cohen, Emaad Khwaja, Youssef Doubli, Salahidine Lemaachi, Chris Lettieri, Charles Masson, Hugo Miccinilli, Elise Ramé, Qiqi Ren, Afshin Rostamizadeh, Jean du Terrail, Anna-Monica Toon, Kan Wang, Stephan Xie, Zongzhe Xu, Viktoriya Zhukova, David Asker, Ameet Talwalkar, Othmane Abou-Amal
2026-04-23
We introduce Toto, a time series forecasting foundation model with 151 million parameters. Toto uses a modern decoder-only architecture coupled with architectural innovations designed to account for specific challenges found in multivariate observability time series data. Toto's pre-training corpus is a mixture of observability data, open datasets, and synthetic data, and is 4-10 larger than those of leading time series foundation models. Additionally, we introduce BOOM, a large-scale benchmark consisting of 350 million observations across 2,807 real-world time series. For both Toto and BOOM, we source observability data exclusively from our own telemetry and internal observability metrics. Extensive evaluations demonstrate that Toto achieves state-of-the-art performance on both BOOM and on established general purpose time series forecasting benchmarks. Toto's model weights, inference code, and evaluation scripts, as well as BOOM's data and evaluation code, are all available as open source under the Apache 2.0 License.
Modulating Language Model Experiences through Frictions
arXiv preprint
2024
Language models are transforming the ways that their users engage with the world. Despite impressive capabilities, over-consumption of language model outputs risks propagating unchecked errors in the short-term and damaging human capabilities for critical thinking in the long-term, particularly in knowledge-based tasks. How can we develop scaffolding around language models to curate more appropriate use? We propose selective frictions for language model experiences, inspired by behavioral science interventions, to dampen misuse. Frictions involve small modifications to a user's experience, e.g., the addition of a button impeding model access and reminding a user of their expertise relative to the model.
Revisiting Cascaded Ensembles for Efficient Inference
arXiv preprint
2024
A common approach to make machine learning inference more efficient is to use example-specific adaptive schemes, which route or select models for each example at inference time. In this work we study a simple scheme for adaptive inference. We build a cascade of ensembles (CoE), beginning with resource-efficient models and growing to larger, more expressive models, where ensemble agreement serves as a data-dependent routing criterion. This scheme is easy to incorporate into existing inference pipelines, requires no additional training, and can be used to place models across multiple resource tiers--for instance, serving efficient models at the edge and invoking larger models in the cloud only when necessary.
Applying interpretable machine learning in computational biology—pitfalls, recommendations and opportunities for new developments
Nature Methods
2024
Recent advances in machine learning have enabled the development of next-generation predictive models for complex computational biology problems, thereby spurring the use of interpretable machine learning (IML) to unveil biological insights. However, guidelines for using IML in computational biology are generally underdeveloped. We provide an overview of IML methods and evaluation techniques and discuss common pitfalls encountered when applying IML methods to computational biology problems. We also highlight open questions, especially in the era of large language models, and call for collaboration between IML and computational biology researchers.
Do llms exhibit human-like response biases? a case study in survey design
Transactions of the Association for Computational Linguistics
2024
One widely cited barrier to the adoption of LLMs as proxies for humans in subjective tasks is their sensitivity to prompt wording—but interestingly, humans also display sensitivities to instruction changes in the form of response biases. We investigate the extent to which LLMs reflect human response biases, if at all. We look to survey design, where human response biases caused by changes in the wordings of “prompts” have been extensively explored in social psychology literature. Drawing from these works, we design a dataset and framework to evaluate whether LLMs exhibit human-like response biases in survey questionnaires
The Impact of Element Ordering on LM Agent Performance
arXiv preprint
2024
There has been a surge of interest in language model agents that can navigate virtual environments such as the web or desktop. To navigate such environments, agents benefit from information on the various elements (e.g., buttons, text, or images) present. It remains unclear which element attributes have the greatest impact on agent performance, especially in environments that only provide a graphical representation (i.e., pixels). Here we find that the ordering in which elements are presented to the language model is surprisingly impactful--randomizing element ordering in a webpage degrades agent performance comparably to removing all visible text from an agent's state representation.